855 projects, posts and guides about Jev, the System One model from TypeSafe AI. Each entry links to its source and shows the cost and speed its author reported.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
I built JevChess ♞: realistic 3D chess in your browser vs Jev, @typesafeai's decision model.
Beginner, Pro or Legendary. Works on your phone. Free, no sign-up.
Play: jevchess.odinachi.space
Open source, contributions welcome 👇
github.com/Odinachi/jevch…
Every day this week, we're launching a new feature @GrepdotAI to help you automate the work that's slowing down your business.
𝗗𝗮𝘆 𝟮: 𝗗𝗲𝗰𝗶𝘀𝗶𝗼𝗻 𝗼𝘂𝘁𝗽𝘂𝘁𝘀 𝗽𝗼𝘄𝗲𝗿𝗲𝗱 𝗯𝘆 𝗝𝗲𝘃
Customers often ask why our agents don't attach confidence levels to their recommendations. My answer has been that LLM confidence levels don't mean much. The model writes a number after the answer, predicting what a confident-sounding score looks like, with a bias toward making humans happy. RLHF pushes models overconfident.
Decision models like Jev by @typesafeai change that. You declare the options up front. Jev returns a probability for each one in a single pass, plus a confidence score derived from how concentrated that distribution is. TypeSafe trained it with RLCD, which rewards calibration instead of rater approval, so decisions at 0.9 should be right about 90% of the time.
In Grep, you can now build agents that use frontier models for the research and diligence, then hand their findings to Jev to make the final decision against your criteria. You set the threshold: above it the agent acts, below it a human reviews.
Tests Jev and other decision models against exact probabilities.
ILIshida Lab
4
Kyle Wild
@dorkitude
Jev isn't tricked by ordering, and the others are.
Tested OpenAI Decisions, Clef-flash, Microsoft-Decision-1, and SubQ Snap.
dorkitude.com/writing/order-…
Introducing Standard One SH: open-weight decision models.
One pass. A probability per option. No text generation.
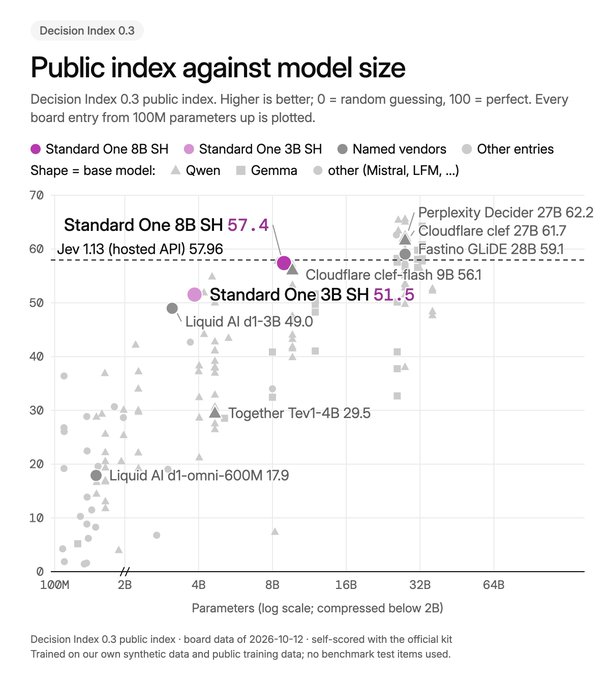
Decision Index 0.3 public index:
- 3B 51.5, highest under 4B vs the Oct 12 board;
- 8B 57.4
Self-scored with the official kit.
Open weights on @huggingface
🧵 1/6