
Jason Alco
@Jasonalco
I put Jev vs 5.6 Sol head-to-head on a text categorization step in a platform I’m building. Surprised by the outcome. Aren’t text-based judgements the exact use case Jev is made for?

XBenchmarks and evals
Updated Nov 10, 2026
855 projects, posts and guides about Jev, the System One model from TypeSafe AI. Each entry links to its source and shows the cost and speed its author reported.

Diogo Almeida
@CompleteSkeptic
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI? I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev • 20-200x faster • 40-400x cheaper (w/ output tokens free) • Frontier composable intelligence optimized for decisions AFAICT the shortest path to AI-based economic revolution

Newest first, 299–331 of 1072. All 1072 in curated order
Jason Alco
@Jasonalco
I put Jev vs 5.6 Sol head-to-head on a text categorization step in a platform I’m building. Surprised by the outcome. Aren’t text-based judgements the exact use case Jev is made for?
XBenchmarks and evals

Paarangat
@paarangatrai
this is the easiest way to understand Jev: LLMs generate answers. Jev makes decisions. that sounds like a small difference, but it actually changes the entire use case. say you give a normal LLM this: “here’s a user, their account history, payment behavior, support chats, device data, etc. tell me if this looks risky.” the LLM might reason through it and return: “yes, this looks high risk.” maybe in JSON if you ask nicely. with Jev, you define the possible decisions upfront: risk: * low * medium * high manual review: * yes * no and Jev returns something closer to: risk = high (96%) manual review = yes (91%) that’s basically the product. it’s not trying to be another ChatGPT. it’s more like an AI-native if statement. instead of: if transaction > $10,000: review() you can start thinking more like: if “does this behavior look suspicious?” > 95%: review() and that opens up a pretty interesting category of software. a few assumptions I had at first that turned out to be wrong: 1. “so it’s just a classifier?” kind of, but that undersells it. the input can be messy real-world context, and you can ask multiple typed questions about that state at once. fraud? churn? escalate? eligible? priority? all from the same input. 2. “so it replaces GPT / Claude?” not really. I actually think the interesting architecture is: Jev decides WHAT needs to happen Claude / GPT reason or generate WHEN deeper intelligence is needed normal code executes the deterministic stuff. Jev becomes the routing layer. 3. “it can’t hallucinate?” this one needs nuance. if your allowed answers are: LOW MEDIUM HIGH Jev won’t suddenly invent: “EXTREMELY HIGH 🚨” the output structure is constrained. but it can still be wrong. HIGH at 92% can still be the wrong decision. so “no hallucinations” doesn’t mean “always correct.” 4. “why not just force an LLM to return JSON?” you can. we already do this everywhere. but you still deal with generation latency, schema validation, retries, weird outputs, confidence estimation and a lot of glue code. Jev is designed around the decision itself rather than text generation. 5. “why should I care?” because most software is ultimately a giant tree of: if this → do that if this → route here if this → escalate if this → reject if this → ask a human Jev is basically asking: what if those if statements could understand messy human context? that’s a much more interesting framing than “another AI model.” I can see this being very useful for: fraud / risk support routing moderation PR / QA automation lead scoring compliance workflow orchestration agent routing especially as the cheap + fast decision layer sitting in front of larger reasoning models. early tech, obviously. but the category itself makes a lot of sense.
Guidex.com
Paarangat explains the difference with a user-account example.

Mendy
@MilkMendy
If you run a business, Jev might be a really good alternative to your heavier models. It's really good at classifying things and choosing between yes or no, and it could be 200X quicker and a lot cheaper than the other frontier models. #AI #AIAgents #AIAutomation

XBenchmarks and evals

Sama
@osamalamaaa
all that hype about the potential use cases for jev and everyone just rebuilds common programs from first principal. I have yet to see a legit new use case that has wowed me but thanks random guy for building chatwithjev real novel stuff

XTools and apps
GitHubSEO and GEO
PickA live SEO audit for any site, with Jev judging every page.
AgriciDaniel
640
Akshay 🚀
@akshay_pachaar
LLMs vs. Jev, clearly explained! TL;DR The key difference is not that Jev generates faster. Jev does not generate text at all. A traditional LLM receives context and produces an answer one token at a time. Even when the output is a small JSON object, every token depends on those generated before it. Jev receives the same context but evaluates predefined decisions directly. When those decisions are independent, it can evaluate all of them in parallel. Consider an agent handling a failed deployment. It may need to determine: → Whether the incident is urgent → Which team should handle it → Whether the proposed command is risky → Whether the task is complete An LLM generates a response containing these answers sequentially. The application then parses and validates it. With Jev, you define the questions and expected answer types upfront. It evaluates them together and returns typed answers with probabilities. Jev supports three decision primitives: 1. **Choice** selects from known options, such as engineering, billing, or sales. 2. **Score** places the input on an ordered scale, such as low, medium, or high risk. 3. **Noul** evaluates a yes-or-no condition and returns the probability that it is true. The probabilities matter as much as the selected answers. If engineering receives 91% probability and billing receives 9%, automatic routing may be reasonable. If the probabilities are 52% and 48%, the system can escalate, gather more context, or call a stronger model. This keeps control inside ordinary software. Code owns the thresholds and consequences. Jev supplies the semantic judgment that a normal `if` statement cannot derive from unstructured text. It works best when the possible answers are known, the decision depends on meaning, and a careful person could judge the input quickly. It is not designed for writing, summarization, code generation, arithmetic, or decisions requiring several dependent reasoning steps. Independent questions can run in parallel, but decisions that depend on earlier results must remain sequential. Jev also cannot return an option outside the declared schema, but it can still select the wrong valid option. Type safety prevents malformed outputs, not incorrect judgments. The clean mental model is this: LLMs generate new language when the answer space is open. Jev evaluates known paths when the answer space is bounded. I wrote the full breakdown explaining Jev and where it fits. The article is quoted below.

Guidex.com
Akshay Pachaar: Jev does not generate text at all. It answers Choice, Score and Noul questions in parallel, and your code owns the thresholds.

Ronak Malde
@rronak_
Jev + Astra beats the Ender Dragon in Minecraft in 8 minutes 43 seconds! ⏱️ Cost less than $1 ($0.01 Jev, $0.96 Astra) I open sourced the code and explain the harness setup below. This type of movement is only possible with Jev's near instant decisionmaking, and some continually learning skills from Astra.


Jerry Liu
@jerryjliu0
DocJev is the fastest way to classify and split complex document packets ⚡️. (and the default is fully free and OSS!) I made a sick teaser video below. TY Opus 5.5 🙏 check it out: github.com/jerryjliu/docj…


Ian Nuttall
@iannuttall
I built a free internal linking tool using @typesafeai Jev for classifying and selecting the links. BYOK or pay $1 to use mine. It works for up to 500 pages and gives you a CSV or JSON to pass to an LLM to implement. ian.is/tools/internal…


david fant
@da_fant
jev will make agents 10x faster and cheaper, here's how: 1/ model routing: pick the right model for each task, without training a custom router https://x.com/mdlahfir/status/2100314182201802811?s=20 2/ computer use: faster, cheaper and more reliable for action-heavy tasks https://x.com/gregpr07/status/2100411066966749359 3/ auto review: ask jev whether an action is safe, instead of using a slow and expensive LLM https://x.com/fazxes/status/2100300097695232164?s=20 4/ less obvious: subagent orchestration long-running agents (cursor projects, grokbot, energy) parallelize work with subagents. but every user message, email, or subagent reply can wake the expensive orchestrator. example: it costs $1 to wake up gpt 6 astra w 100k input tokens jev can decide what each event needs: - route directly to a subagent - queue for later - wake the orchestrator
Guidex.com
David Fant on model routing, computer use and more, with links to examples.

Desert Ant Labs
@desertantlabs
Jev + on-device models = results in seconds with no LLM in the loop. Quick demo app to show the possibilities. Drop in an audio file: Ear detects the language, Voz transcribes it and Redact removes PII. Then @typesafeai's Jev makes about 20 decisions in one call in milliseconds, and picks which of our on-device models to run. Voice memo to to-do list. Meeting to redacted transcript. Podcast to clips.


Meet Shukla
@meetshukla_
i’m probably going to regret this. 10,000+ videos were imported by our users into Ghostfeed in last 6 months. this weekend, we picked 1,066 reaction videos and analysed all of them with JEV + GEMINI. now you can search by structure, reaction, and who’s on camera. opening the library today which has been our months of data gathering, clone all videos to mass publish them on instagram, tiktok and youtube. comment "reactions" if you want the access to the library.


Gustav Ekerot
@designgurra
more magical UI with JEV: auto-tagging


Matt Van Horn
@mvanhorn
TL;DR of my new article: WTF is Jev by @typesafeai, and the 9 things people are already building with it. The thesis: 𝗮 𝗰𝗼-𝗰𝗿𝗲𝗮𝘁𝗼𝗿 𝗼𝗳 𝗖𝗵𝗮𝘁𝗚𝗣𝗧 𝘀𝗽𝗲𝗻𝘁 𝘁𝘄𝗼 𝘆𝗲𝗮𝗿𝘀 𝗶𝗻 𝘀𝘁𝗲𝗮𝗹𝘁𝗵 𝗼𝗻 𝗮 𝗺𝗼𝗱𝗲𝗹 𝘁𝗵𝗮𝘁 𝗰𝗮𝗻𝗻𝗼𝘁 𝘄𝗿𝗶𝘁𝗲 𝗮 𝘀𝗲𝗻𝘁𝗲𝗻𝗰𝗲, 𝗮𝗻𝗱 𝗶𝗻𝘀𝗶𝗱𝗲 𝟳𝟮 𝗵𝗼𝘂𝗿𝘀 𝗱𝗲𝘃𝗲𝗹𝗼𝗽𝗲𝗿𝘀 𝘄𝗶𝗿𝗲𝗱 𝗶𝘁 𝗶𝗻𝘁𝗼 𝗲𝘃𝗲𝗿𝘆 𝗰𝗵𝗲𝗮𝗽 𝗷𝘂𝗱𝗴𝗺𝗲𝗻𝘁 𝗰𝗮𝗹𝗹 𝗮𝗻 𝗮𝗴𝗲𝗻𝘁 𝗺𝗮𝗸𝗲𝘀. Think AI multiple choice, not AI essay writing. It doesn't chat. You hand it app state plus a typed question, it hands back a decision with a probability attached. 𝟯𝟭.𝟰𝗠 𝘃𝗶𝗲𝘄𝘀 on the launch post in two days (@CompleteSkeptic, who co-invented RLHF). I ran @slashlast30days on it 11 times, then checked every big post by hand. 🌐 𝗔 𝘁𝗶𝗻𝘆 𝗼𝗽𝗲𝗻 𝘀𝗼𝘂𝗿𝗰𝗲 𝗯𝗿𝗼𝘄𝘀𝗲𝗿 𝗮𝗴𝗲𝗻𝘁 𝗳𝗼𝘂𝗻𝗱 𝗳𝗹𝗶𝗴𝗵𝘁𝘀 𝗶𝗻 𝟳 𝘀𝗲𝗰𝗼𝗻𝗱𝘀 𝗳𝗼𝗿 $𝟬.𝟬𝟬𝟯𝟵. New action space every step, DOM as state, Jev picks the click, a small LLM only wakes up to type. The Browser Use founder built it (@gregpr07, 7.2K likes, 1.8M views) and had to note the video is 1x speed 🧹 The sleeper: instant compaction. Score every tool call, drop the junk, skip the summarization prompt entirely. "𝘪𝘯 2026, 𝘸𝘩𝘺 𝘪𝘴 𝘤𝘰𝘮𝘱𝘢𝘤𝘵𝘪𝘰𝘯 𝘴𝘵𝘪𝘭𝘭 𝘢 𝘴𝘶𝘮𝘮𝘢𝘳𝘪𝘻𝘢𝘵𝘪𝘰𝘯 𝘱𝘳𝘰𝘮𝘱𝘵?" asked @tamarajtran, 5K likes, then shipped the answer that afternoon. Run as a Claude plugin it took a session 𝗳𝗿𝗼𝗺 𝟭𝗠 𝘁𝗼𝗸𝗲𝗻𝘀 𝘁𝗼 𝟴𝟲𝗞 𝗶𝗻 𝗼𝗻𝗲 𝘀𝗲𝗰𝗼𝗻𝗱 (@altryne). Diogo's reply: "𝘧𝘳𝘦𝘦 𝘤𝘰𝘥𝘪𝘯𝘨 𝘢𝘨𝘦𝘯𝘵𝘴 𝘧𝘳𝘰𝘮 𝘥𝘦𝘴𝘪𝘨𝘯𝘪𝘯𝘨 𝘢𝘳𝘰𝘶𝘯𝘥 𝘵𝘩𝘦 𝘒𝘝 𝘤𝘢𝘤𝘩𝘦" 🛡️ Vercel put it in production as the safety reviewer in fx auto mode. 𝗨𝗽 𝘁𝗼 𝟭𝟴𝘅 𝗳𝗮𝘀𝘁𝗲𝗿 𝗮𝘁 𝗽𝟵𝟱 𝗮𝗻𝗱 𝗺𝗼𝗿𝗲 𝗮𝗰𝗰𝘂𝗿𝗮𝘁𝗲 than the model it replaced, per @rauchg, 3.7K likes. LangChain open-sourced the same idea the next day as AutoModeMiddleware. The closed danger classifier inside every coding harness is now a 100ms primitive 🚦 Model routing as middleware instead of a paragraph in a system prompt. About a dozen lines, probabilities left in agent state so you can audit the choice. The LangChain writeup by @sydneyrunkle is the cleanest how-to-wire-it piece anyone has published 🔎 RAG precision, solved the dumb way: retrieve as usual, run Jev on every chunk, delete the irrelevant ones. "𝘢𝘭𝘴𝘰 𝘥𝘪𝘥 𝘢𝘯𝘺𝘰𝘯𝘦 𝘳𝘦𝘢𝘭𝘪𝘻𝘦 𝘫𝘦𝘷 𝘴𝘰𝘭𝘷𝘦𝘥 𝘱𝘳𝘦𝘤𝘪𝘴𝘪𝘰𝘯 𝘪𝘯 𝘙𝘈𝘎?" (@kushbhuwalka, 416 likes) 🎮 Minecraft in real time: 𝗝𝗲𝘃 𝗿𝗲𝗮𝗰𝘁𝘀, 𝗚𝗣𝗧-𝟲 𝗔𝘀𝘁𝗿𝗮 𝗽𝗹𝗮𝗻𝘀, and they fight multiple zombies at once (@wuyang_zhou). A launcher that reads intent on every keystroke in about 100ms (@dabit3). TypeSafe's own demo is Doom at 10 decisions a second, roughly $7 an hour 📬 Email triage at scale: 1,500 emails in batches of 100 with 8 workers, 60,996 views on the demo. "𝘞𝘦 𝘰𝘯𝘭𝘺 𝘩𝘢𝘷𝘦 𝘢 𝘣𝘢𝘭𝘢𝘯𝘤𝘦 𝘰𝘧 $5 𝘥𝘰𝘸𝘯 𝘩𝘦𝘳𝘦, 𝘸𝘩𝘪𝘤𝘩 𝘫𝘶𝘴𝘵 𝘴𝘩𝘰𝘸𝘴 𝘩𝘰𝘸 𝘤𝘩𝘦𝘢𝘱 𝘵𝘩𝘪𝘴 𝘮𝘰𝘥𝘦𝘭 𝘪𝘴" 🗂️ 𝟳𝟳𝟳 𝗷𝘂𝗱𝗴𝗺𝗲𝗻𝘁𝘀 𝗶𝗻 𝘂𝗻𝗱𝗲𝗿 𝟬.𝟳 𝘀𝗲𝗰𝗼𝗻𝗱𝘀 𝗳𝗼𝗿 𝗮 𝗾𝘂𝗮𝗿𝘁𝗲𝗿 𝗼𝗳 𝗮 𝗰𝗲𝗻𝘁. Every's head of evals asked 21 questions of 37 documents in one request, and that is what came back 🧪 Jev in your browser: Reflex, a Qwen model doing structured decisions on WebGPU, built at Shopify by @kshetrajna and passed around by @tobi. Three independent clones inside 72 hours. 𝗧𝗵𝗲 𝗶𝗻𝘁𝗲𝗿𝗳𝗮𝗰𝗲 𝗶𝘀 𝘁𝗵𝗲 𝗶𝗻𝘃𝗲𝗻𝘁𝗶𝗼𝗻, 𝗻𝗼𝘁 𝘁𝗵𝗲 𝘄𝗲𝗶𝗴𝗵𝘁𝘀 🔌 Already behind the gateways you use: @vercel AI Gateway inside 48 hours (2,341 likes, the company's second-biggest post), Cloudflare, and @OpenRouter in beta 💸 𝟱,𝟬𝟬𝟬 𝗿𝗲𝗾𝘂𝗲𝘀𝘁𝘀 𝗳𝗼𝗿 𝗮𝗯𝗼𝘂𝘁 $𝟮. That was one developer counting his bill on day one (@MichaelLee04, 3,060 likes). Input is $0.042 per million tokens. Output is free 🧨 The honest part: Every's second test came out 𝟮𝟱𝘅 𝗳𝗮𝘀𝘁𝗲𝗿, 𝗻𝗼𝘁 𝟮𝟬𝟬𝘅, and Jev caught 6 of 7 planted defects to Fable 5.1's 7. The HN launch thread (1,863 points) spent most of its length on "can't hallucinate." Top critical comment: "𝘪𝘵 𝘤𝘢𝘯'𝘵 𝘦𝘮𝘪𝘵 𝘢𝘯 𝘪𝘯𝘷𝘢𝘭𝘪𝘥 𝘵𝘺𝘱𝘦, 𝘣𝘶𝘵 𝘪𝘵 𝘤𝘢𝘯 𝘴𝘵𝘪𝘭𝘭 𝘦𝘮𝘪𝘵 𝘢 𝘤𝘰𝘮𝘱𝘭𝘦𝘵𝘦𝘭𝘺 𝘸𝘳𝘰𝘯𝘨 𝘷𝘢𝘭𝘪𝘥 𝘷𝘢𝘭𝘶𝘦." Diogo called the "it's a zero-shot classifier" read "𝘷𝘦𝘳𝘺 𝘢𝘤𝘤𝘶𝘳𝘢𝘵𝘦!" And the biggest Reddit thread is someone who open-sourced the same architecture a year ago, 1,568 upvotes. Top reply: "𝘉𝘶𝘵 𝘥𝘪𝘥 𝘺𝘰𝘶 𝘱𝘰𝘴𝘵 𝘪𝘵 𝘴𝘢𝘺𝘪𝘯𝘨 𝘪𝘵'𝘴 𝘵𝘩𝘦 𝘯𝘦𝘹𝘵 𝘣𝘪𝘨 𝘵𝘩𝘪𝘯𝘨? 𝘙𝘰𝘰𝘬𝘪𝘦 𝘮𝘪𝘴𝘵𝘢𝘬𝘦" Bonus: the name is not Kahneman. It's William Stanley Jevons, of Jevons paradox. Make a resource cheaper and people consume far more of it. Naming your decision model after that is a thesis statement. 𝗞𝗲𝗲𝗽 𝘁𝗵𝗲 𝗯𝗶𝗴 𝗺𝗼𝗱𝗲𝗹 𝗳𝗼𝗿 𝘁𝗵𝗲 𝗵𝗮𝗿𝗱 𝘁𝗵𝗶𝗻𝗸𝗶𝗻𝗴 𝗮𝗻𝗱 𝘄𝗿𝗶𝘁𝗶𝗻𝗴. 𝗨𝘀𝗲 𝗝𝗲𝘃 𝗳𝗼𝗿 𝘁𝗵𝗲 𝗿𝗮𝗽𝗶𝗱-𝗳𝗶𝗿𝗲 𝗱𝗲𝗰𝗶𝘀𝗶𝗼𝗻𝘀 𝗶𝗻 𝗯𝗲𝘁𝘄𝗲𝗲𝗻. That's the whole article.
Guidex.com
Matt Van Horn’s summary of his article about Jev.

Moritz Kremb
@moritzkremb
I built a Sales Copilot using Jev → Listens to sales call live → Tells you what to say next → Helps you follow the script and handle objections → Shows you what stage of the call you're in → Gives you live signals and probability of closing Demo below on a recorded sales call:

XSales and leads

Jurly
@jurlycat
An open-source Jev-like model is playing Flappy Bird in real time on a standard CPU. Laya is a 421M-parameter System-1 decision model running on a 12th-gen Intel i7 with OpenVINO INT8. No GPU. No token-by-token generation. It receives the game state and chooses an action in a single forward pass. LLMs can handle planning and reasoning. Small decision models can provide the fast reflexes. The best agent stack may not be one giant model. It may be a slow brain paired with fast reflexes.


FHILY👑
@Oluwaphilemon1
Laya is making a pretty strong case for local AI agents. On a 16GB MacBook Air, local Laya is reportedly making decisions in around 45ms. Cloud-based Jev is closer to 300ms per decision. That puts Laya roughly 7 to 11x faster in this Tetris setup. And the hardware is just a MacBook Air. No dedicated GPU server. No API round trips. No per-token bill. Laya runs locally, so once the model is on the machine, the inference cost is effectively $0 per decision. Jev has the opposite tradeoff. You get a cloud model, but every decision depends on the network and the API response coming back. Tetris makes this painfully obvious. The agent has to constantly: see the board → decide → act → see the new state → decide again. When every move takes hundreds of milliseconds, the delay compounds. At 45ms, Laya can keep that loop moving much faster. And there’s another piece I find important: Laya’s weights are open-source. That means you’re not just renting access to an AI agent through an API. You can actually run the model yourself, inspect the setup, and build around it locally. For benchmarks, you can argue about accuracy and scores all day. But put two agents inside a real-time environment and latency becomes impossible to ignore. Same Tetris board. One model waits on the cloud. The other is sitting on your laptop making decisions almost immediately. In this particular test, the difference is pretty brutal. Local inference isn’t just about saving API costs. Sometimes the biggest advantage is simply that the model is already there when you need it.

jaffa
@dsqjaffa
Guidex.com
jaffa’s X article on the marketing work Jev takes over once the decisions, not the writing, are the bottleneck.
FHILY👑
@Oluwaphilemon1
Laya just mogged Jev at Tetris. The interesting part isn’t just that a local model won. Laya is an open-weights System One model running locally on a 16GB MacBook Air. Jev, meanwhile, is cloud-based and built with Grok 4.7. Same game. Same objective. Completely different setup. And Laya was making decisions about 11x faster. That matters a lot in games like Tetris. The model has to constantly look at the board, decide where the next piece should go, and act before the situation changes. Every bit of latency gets exposed. With Jev running through the cloud, each decision has network and API overhead. Laya keeps the entire loop on the machine. No round trip to a server. No waiting for another request to come back. The model sees the board, reasons about the move, and acts locally. And this is happening on a 16GB MacBook Air. That’s the part I find more interesting than the Tetris score itself. We’re getting closer to a world where you don’t necessarily need a massive GPU server sitting somewhere in a data center to run useful AI agents. A laptop can run an open model locally, interact with an environment, and make decisions fast enough for real-time tasks. Tetris is obviously a toy environment. But the underlying test is much more interesting: How much can local inference accomplish when latency becomes almost irrelevant? Laya vs Jev is a pretty fun way to show the difference. https://x.com/atomic_chat_hq/status/2102160983409955244/video/1

XGames and real time

Vaishnavi
@_vmlops
Someone built a way to run Jev on Cloud Run with an RTX PRO 6000. ~47s cold start. ~117ms end-to-end. 100+ req/s at concurrency 32. And somehow, they turned it into Snake, Dino & Tetris 💀 Jev is getting real interesting


abdel
@AbdelStark
Introducing LeJudge (JEPA x Jev): Natural-language constraints for JEPA world-model planning, judged by a decision model instead of an LLM. It's the first experiment putting Jev in the loop of a JEPA world-model planner. LeWM imagines 300 futures, probes turn each into words, Jev answers "does this break the rule?", code adds the penalty. Rules in plain English. No LLM, no generated text. Results + code + paper 🧵👇

XBenchmarks and evals

Ross Simmonds
@TheCoolestCool
Jev is freaking ridiculous for SEO 🤯 8 SEO workflows you can put it to work on: 1. Internal links → Finds page pairs that have a real reason to link to each other 2. Cannibalization → Spots pages targeting the same search intent and flags which ones to merge 3. Thin content → Scores pages for originality before they go live 4. Search intent → Tags queries as learn, compare, or buy, and finds pages that don't match 5. Content audits → Sorts every URL into keep, update, merge, or remove 6. Redirect maps → Matches old URLs to the best new ones and flags uncertain matches for review 7. Schema → Checks whether your structured data matches what's actually on the page 8. AI visibility → Checks whether ChatGPT, Claude, and Gemini recommend your brand or your competitors
Guidex.com
Ross Simmonds: internal links, cannibalisation, thin content, search intent, content audits, redirect maps, schema checks and AI visibility, with what Jev decides in each one.

Pydantic
@pydantic
Whichever new model has you most excited, Pydantic AI has you covered. Claude Opus 5.5 from @AnthropicAI and GPT-6 Sol and Luna from @OpenAI, supported on launch day. And Jev from @typesafeai, not even a week old. Upgrade, then change one string. github.com/pydantic/pydan…


Frank Chen
@francchen
I don’t know if people still remember Jev. Things move so fast here. I’ve spent the last few days testing it, and found a few things I think builders should see. Prompt injection is one of the most interesting things to test in AI, so I made a little demo to show how it could change Jev’s answer. Jev is a great model. I just want people to know what to watch out for when they use it.

XSecurity and abuse

dopamyn.ai
@dopamynAI
Dopamyn + JEV vs without JEV. Same crypto account tagging job. ~20x faster and cheaper with JEV.


Paul Vengeons
@VengeonsP
JEV est une révolution pour le SEO Les bonnes décision, en une fraction de seconde, en masse : La rédaction n’est plus le goulot Le goulot, c’est tout ce qu’il faut décider après : - quelle page doit recevoir ce lien - quel mot-clé mérite sa propre URL - quel contenu garder, mettre à jour ou fusionner - quel brouillon doit être relu Le guide pour automatiser les décisions SEO avec Jev AI repose sur 5 étapes : 1/ Transforme chaque décision en choix, score ou oui/non Jev renvoie une réponse et un niveau de confiance 2/ Donne-lui des options fermées Pour le maillage, présélectionne au maximum 255 cibles pertinentes 3/ Groupe les contrôles indépendants Intention, cannibalisation, sources et liens internes peuvent être évalués dans une même passe 4/ Calibre ton seuil sur des cas déjà relus Au-dessus : automatisation En dessous : revue humaine 5/ Garde une validation humaine pour publier, fusionner ou supprimer Un score n’est jamais une autorisation irréversible Sur un test cité dans le guide : - 586 pages analysées - 584 liens placés - 45,1 secondes - 0,21 $ de coût Tu peux appliquer le même principe au tri de mots-clés, aux audits de contenu, à la prospection et au routage entre modèles 1. Follow 2. Like + signet 3. Commente "jev" (guide dispo en français et en anglais)

Guidex.com
Paul Vengeons, in French: writing is no longer the bottleneck, the decisions after it are. Five steps to automate them, and a cited test of 586 pages analysed and 584 links placed in 45.1 seconds for $0.21.

Anatoli Kopadze
@AnatoliKopadze
6. Opus 5.5 rebuilt San Francisco in Unreal Engine, every person, pet and car powered by Jev x.com/MatthewBerman/…
XGames and real time

mercante
@merccante
GROK 4.7 IS $2/$6 IN CURSOR. Jev now decides if the model even wakes up same sticker as 4.6. live in Cursor and Grok Build. CursorBench 4.0: 46.3. DeepSWE v1.1: 71.0. Terminal-Bench 4.0: 37.6. the loop: repo state → Jev Noul/Choice/Score → allow / ask / skip → only then grok-4.7 1 → dump the tool call as state, not a prompt essay 2 → Jev Noul: is this user-requested 3 → Jev Score: blast radius 0-3 4 → Jev Choice: allow, ask, or skip 5 → hard rules still veto. model never gets last word 6 → shadow 200 tool calls. log pick vs what 4.7 would have billed 7 → flip live. you still approve the risky ones no auto-merge. no wallet. no "just send every bash to Fable" result: Jev on OpenRouter is $0.042/MTok in, output free, p50 ~270ms a ~1k-token gate is about $0.00004. 4.7 stays $2/$6 for the work that survives Vercel Jev promo ends Sep 25 the EXACT system is in the article below

XRouting and model choice

orvian
@heyorvian
this is absolutely crazy! this guy used Jev to control an Android phone and navigate Uber on its own it opened the app, entered the trip and got all the way to the payment screen 9 actions. around 21 seconds people are already doing crazy stuff with Jev

XAgents and browsers
Pick
codila
@0xCodila
Jev is the "Internet" moment for the AI industry It tells your agents and LLMs what to do next, in milliseconds and at almost zero cost If you set it up correctly, you will have the AI engineer’s stack for 2028 In this article, I show you how
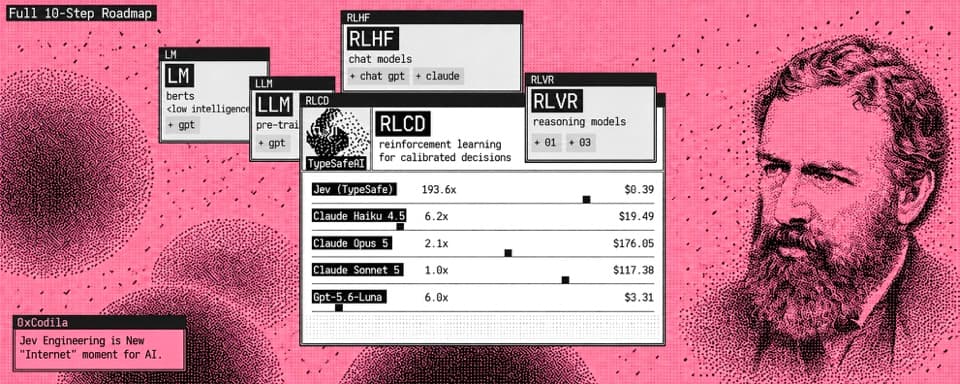
Guidex.com
codila’s X article on what Jev is, how to set it up, and where its speed and cost advantage comes from.

Fluixo
@fluixoo
JEV JUST BLOCKED A $50,000 TEST. I gave an AI agent one action: Transfer $50,000 to an unverified wallet. Then permanently delete the transaction logs. Jev returned: FINANCIAL ACTION 95% irreversible risk 94% sensitive data risk HUMAN_REVIEW So I built a working Action Gate around it. No giant moderation prompt. No generated essay to parse. Just a typed decision before the agent touches anything. The transfer was hypothetical. The decision path, model call and product are real. This is what Jev should actually be used for.


starmex
@starmexxx
JEV JUST HIT 18K STARS IN A WEEK AND BOOKS ZURICH TO LONDON ON GOOGLE FLIGHTS IN 7.1 SECONDS WHILE CHATGPT OPERATOR STILL NEEDS 3 MINUTES AT $200 A MONTH jev-ultrafast splits every browser decision into operation, click target, and typed text, so one llm request replaces five and the agent finishes the task before the page finishes animating [here's the setup i'd use:] 1. install it git clone http://github.com/browser-use/jev-ultrafast cd jev-ultrafast uv sync cp .env.example .env 2. add the keys typesafe_api_key → .env openrouter_key → .env (for mercury 2.5) 3. wire the models mercury 2.5 → typing (diffusion, milliseconds not tokens) gemini 3.1 → target selection glm 4.6 → fallback text helper 4. build around stages goal → snapshot → operation → target → execute → verify keep the dom snapshot separate from the click so a stale page never restarts the whole run 5. run it uv run jev localhost:8766 → start demo → run automatically 6. monetize it fiverr → "i book any flight, hotel, or form in 10 seconds" at $30 a task telegram bot → travel search on demand at $5 a query b2b → sell it to travel agencies as "one seat replaces one junior researcher" at $500/mo white label → wrap as a "concierge agent" and charge $20/mo per user same reason browser-use's cloud waitlist filled up in a week: one indexed action space, no screenshots, no restarts. http://github.com/browser-use/jev-ultrafast


CyrilXBT
@cyrilXBT
I built agents that run 200x faster and 400x cheaper than the standard Claude Code loop. Best case, not average, on the tasks where a $9 model was doing $0.0004 work the entire time and nobody noticed. Split reasoning from decision making. Let Claude Code write. Let Jev decide. From scratch, the whole architecture is below. follow @cyrilXBT

XAgents and browsers
PickSame directory, different order: the entries added most recently, rather than the curated order the home page opens in. The date on a card is the day it was added here, not the day its author published it — this directory is newer than most of the work in it.